Introduction
Gymnasium/MuJoCo is a set of robotics-based reinforcement learning environments using the MuJoCo physics engine, with various goals for the robot to learn, such as standing up, running quickly, or moving an arm to a point.
A quick history of MuJoCo environments
The MuJoCo environments were originally introduced as version 0 in gym==0.0.1 back in 2016, and were shortly followed by version 1 (gym==0.1.0) to address several configuration errors.
In 2018, version 2 was released in gym==0.9.5, bringing major backend improvements using the mujoco-py>=1.5 simulator.
Version 3 (gym==0.12.0 in 2018) offered increased customization options, enabling users to modify parts of the environment such as the reward function and slight adjustments to the robot model.
After Google DeepMind acquired MuJoCo, open-sourced the code and released a dedicated Python module (mujoco), version 4 ported the environments to the new mujoco>=2.2.0 simulator, but removed the capability to slightly modify the environment.
The models in Gymnasium/MuJoCo were made around 2012; they pre-date the “modern” robotics revolution and are not realistic relative to actual robot systems.
All releases since version 1 provide useful additional customization options, back-end improvements and bug fixes, but use the same unrealistic robot models.
MuJoCo v5
Over time, the MuJoCo environments have become standard testing environments in RL, used in hundreds if not thousands of academic papers at this point. They have provided a standard set of difficult-to-solve robotic environments, and have been a cornerstone in the development and evaluation of RL methods.
However, as RL methods continue to improve, the necessity for more complex robotic environments to evaluate them has become evident with state-of-the-art training algorithms, such as TD3 and SAC, being able to solve even the most complex of the MuJoCo problems.
We are pleased to announce version 5 of the Gymnasium/MuJoCo environments, released with gymnasium==1.0.0, with significantly increased customizability, bug fixes and overall faster step and reset speed.
pip install "gymnasium[mujoco]>=1.0.0"
import gymnasium as gym

env = gym.make("Humanoid-v5")
Key features
Example: using third-party MuJoCo robot models
For those looking for more complex real-world robot MuJoCo models, v5 now supports custom robot models for each environment. Below, we show how this can be achieved using models from the MuJoCo Menagerie project.
Depending on the robot type, we recommend using different environment models: for quadruped → Ant-v5, bipedal → Humanoid-v5 and swimmer / crawler robots → Swimmer-v5.
However, it will be necessary to modify certain arguments in order to specify the desired behavior. The most commonly changed arguments are:
xml_file: Path to the MuJoCo robot (MJCF or URDF file).frame_skip: The number of MuJoCo simulation steps per environment step, which sets the duration between steps, dt = frame_skip * model.opt.timestep. We recommend choosing frame_skip so that dt is in the range [0.01, 0.1]; smaller values allow more precise movements but require more actions to reach a goal.ctrl_cost_weight: The weight of control cost in the reward function, set it according to the needs of the robot. We recommend setting it to 0 at first for prototyping and increasing it as needed.healthy_z_range: The upper and lower limit the robot can be at without it being “unhealthy”; set it according to the height of the robot.
For more information on all the arguments, see the documentation pages of Ant, Humanoid and Swimmer.
env = gym.make('Ant-v5', xml_file='./mujoco_menagerie/anybotics_anymal_b/scene.xml', ctrl_cost_weight=0.001, healthy_z_range=(0.48, 0.68), render_mode='human')
Here, we change the xml_file argument to load the new model, set the healthy_z_range because the robot has a different height than the default Ant robot, and reduce ctrl_cost_weight. In general, the healthy_z_range will need to be changed to fit each robot.
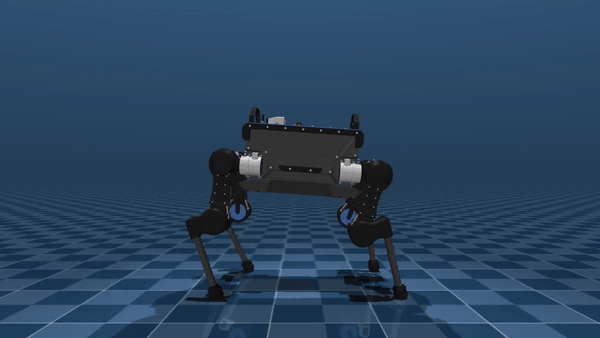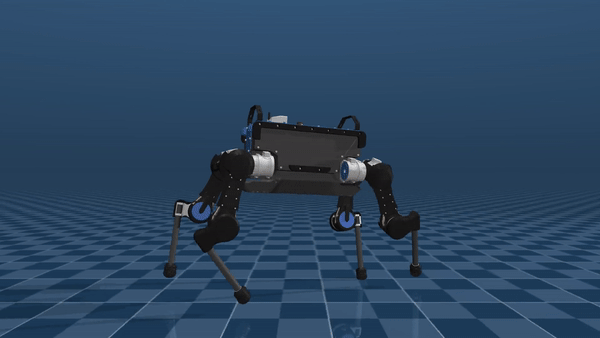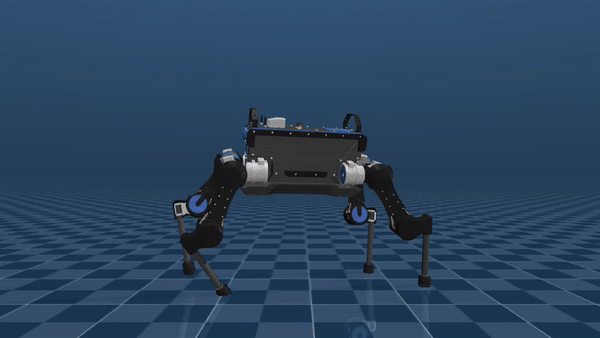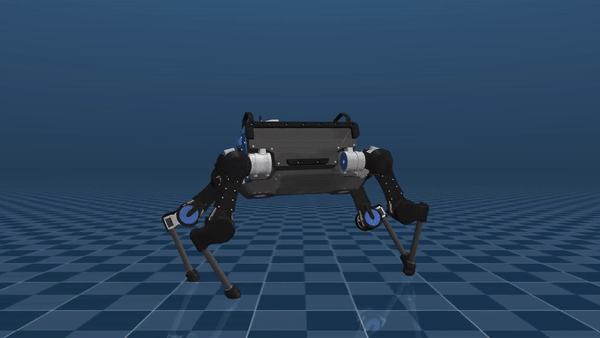
env = gym.make('Ant-v5', xml_file='./mujoco_menagerie/unitree_go1/scene.xml', healthy_z_range=(0.195, 0.75), ctrl_cost_weight=0.05)
The Go1 is a smaller quadruped, so the healthy_z_range is lowered to match its height, and the ctrl_cost_weight is increased to penalize large actions.

env = gym.make('Humanoid-v5', xml_file='./mujoco_menagerie/robotis_op3/scene.xml', healthy_z_range=(0.275, 0.5), include_cinert_in_observation=False, include_cvel_in_observation=False, include_qfrc_actuator_in_observation=False, include_cfrc_ext_in_observation=False, ctrl_cost_weight=0, contact_cost_weight=0)
For the OP3 humanoid, we disable the cinert, cvel, qfrc_actuator and cfrc_ext observations, as these are designed around the default Humanoid model and aren’t needed for this robot. We also set the control and contact costs to 0 for prototyping.
For a more detailed tutorial, see loading quadruped models.
Full Changelog
For more information about the development of the Gymnasium/MuJoCo-v5 environments and a complete changelog, check the GitHub PR.